Anthropic released Claude Opus 5.5 today. It’s the new flagship, and the pitch is simple: it beats Opus 5 on most things while costing less and responding faster. Usually you only get one of those at a time.
What actually changed
The biggest gains are in agentic coding, computer use, and general knowledge work. Anthropic also says the model holds up better on long-running tasks and large codebases, which is where earlier models tended to lose track of what they were doing a few hours in.
A couple of smaller changes I’m happy to see. Answers are shorter and read more naturally, with less padding. Prompt injection resistance is at least as good as Opus 5, and in their behavioral audits the model tried to work around its boundaries 85% less often than its predecessor.
On cost and speed, Anthropic claims roughly 40% lower cost on typical workloads and more than 30% faster output generation compared to Opus 5.
The examples that caught my eye
One early-access tester ran a 680,000-line code migration in under a day. In Anthropic’s own test, the model rewrote HAProxy from C to Rust in 9.5 hours. For comparison, Fable 5.1 needed about 12 hours for the same job, and Opus 5.5 did it at around half the cost.
These are vendor-picked showcases, so take them as a sense of what’s possible rather than what you’ll get every time. Still, a full proxy rewrite in a single working day is a good sign for anyone planning big refactors.
Pricing
The API price dropped across the board:
| Opus 5.5 | Opus 5 | |
|---|---|---|
| Input, per 1M tokens | $4 | $5 |
| Output, per 1M tokens | $20 | $25 |
| Cache reads, per 1M tokens | $0.20 | $0.50 |
Cache writes are $5 per million tokens. There’s also a fast mode at $8 input and $40 output that runs up to 2.5x quicker, if latency matters more than the bill.
The model ID is claude-opus-5-5, and it’s available on the Claude Platform, AWS, Google Cloud, and Microsoft Azure.
Benchmarks
The headline numbers:
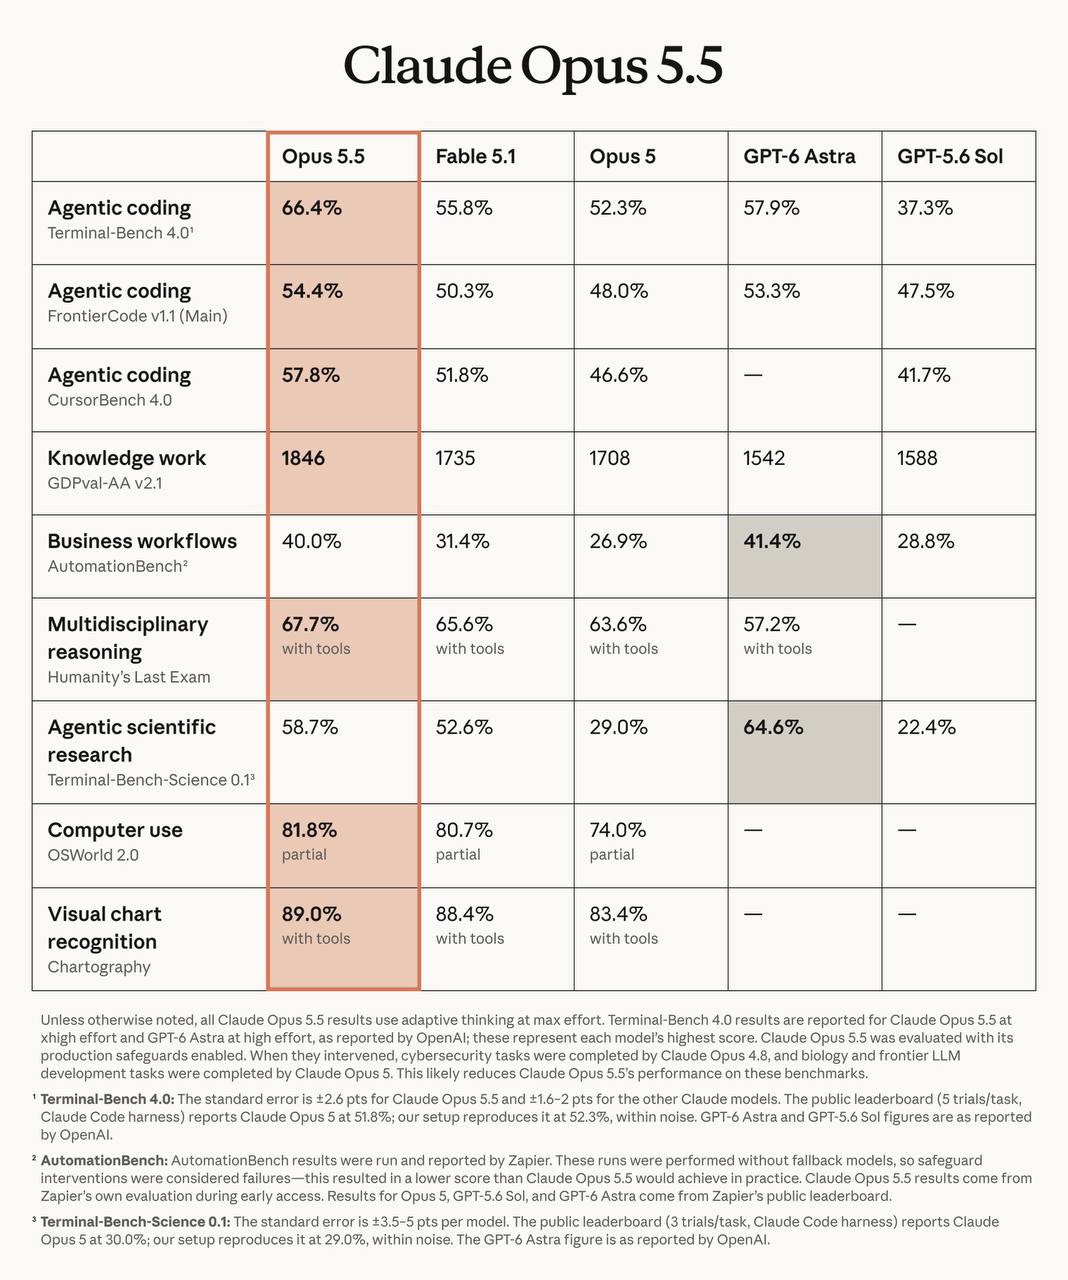
- Terminal-Bench 4.0: 66.4%, up from 52.3% for Opus 5 and ahead of GPT-6 Astra at 57.9%
- FrontierCode v1.1: 54.4%
- CursorBench 4.0: 57.8%
- Humanity’s Last Exam: 67.7% with tools
- OSWorld 2.0 (computer use): 81.8%
It doesn’t win everything. GPT-6 Astra still leads on AutomationBench (41.4% vs 40.0%) and on Terminal-Bench-Science (64.6% vs 58.7%). I like that Anthropic kept those rows in the table instead of quietly dropping them.
What’s next
Anthropic confirmed that Claude Sonnet 5.5 and Haiku 5.5 are coming in the next few weeks. If the price and speed improvements carry over to the smaller models, that’s probably the bigger story for most production workloads.